Sample projects
Two sample projects come with KPD. Open them with File → Open project…
Retail Orders Platform
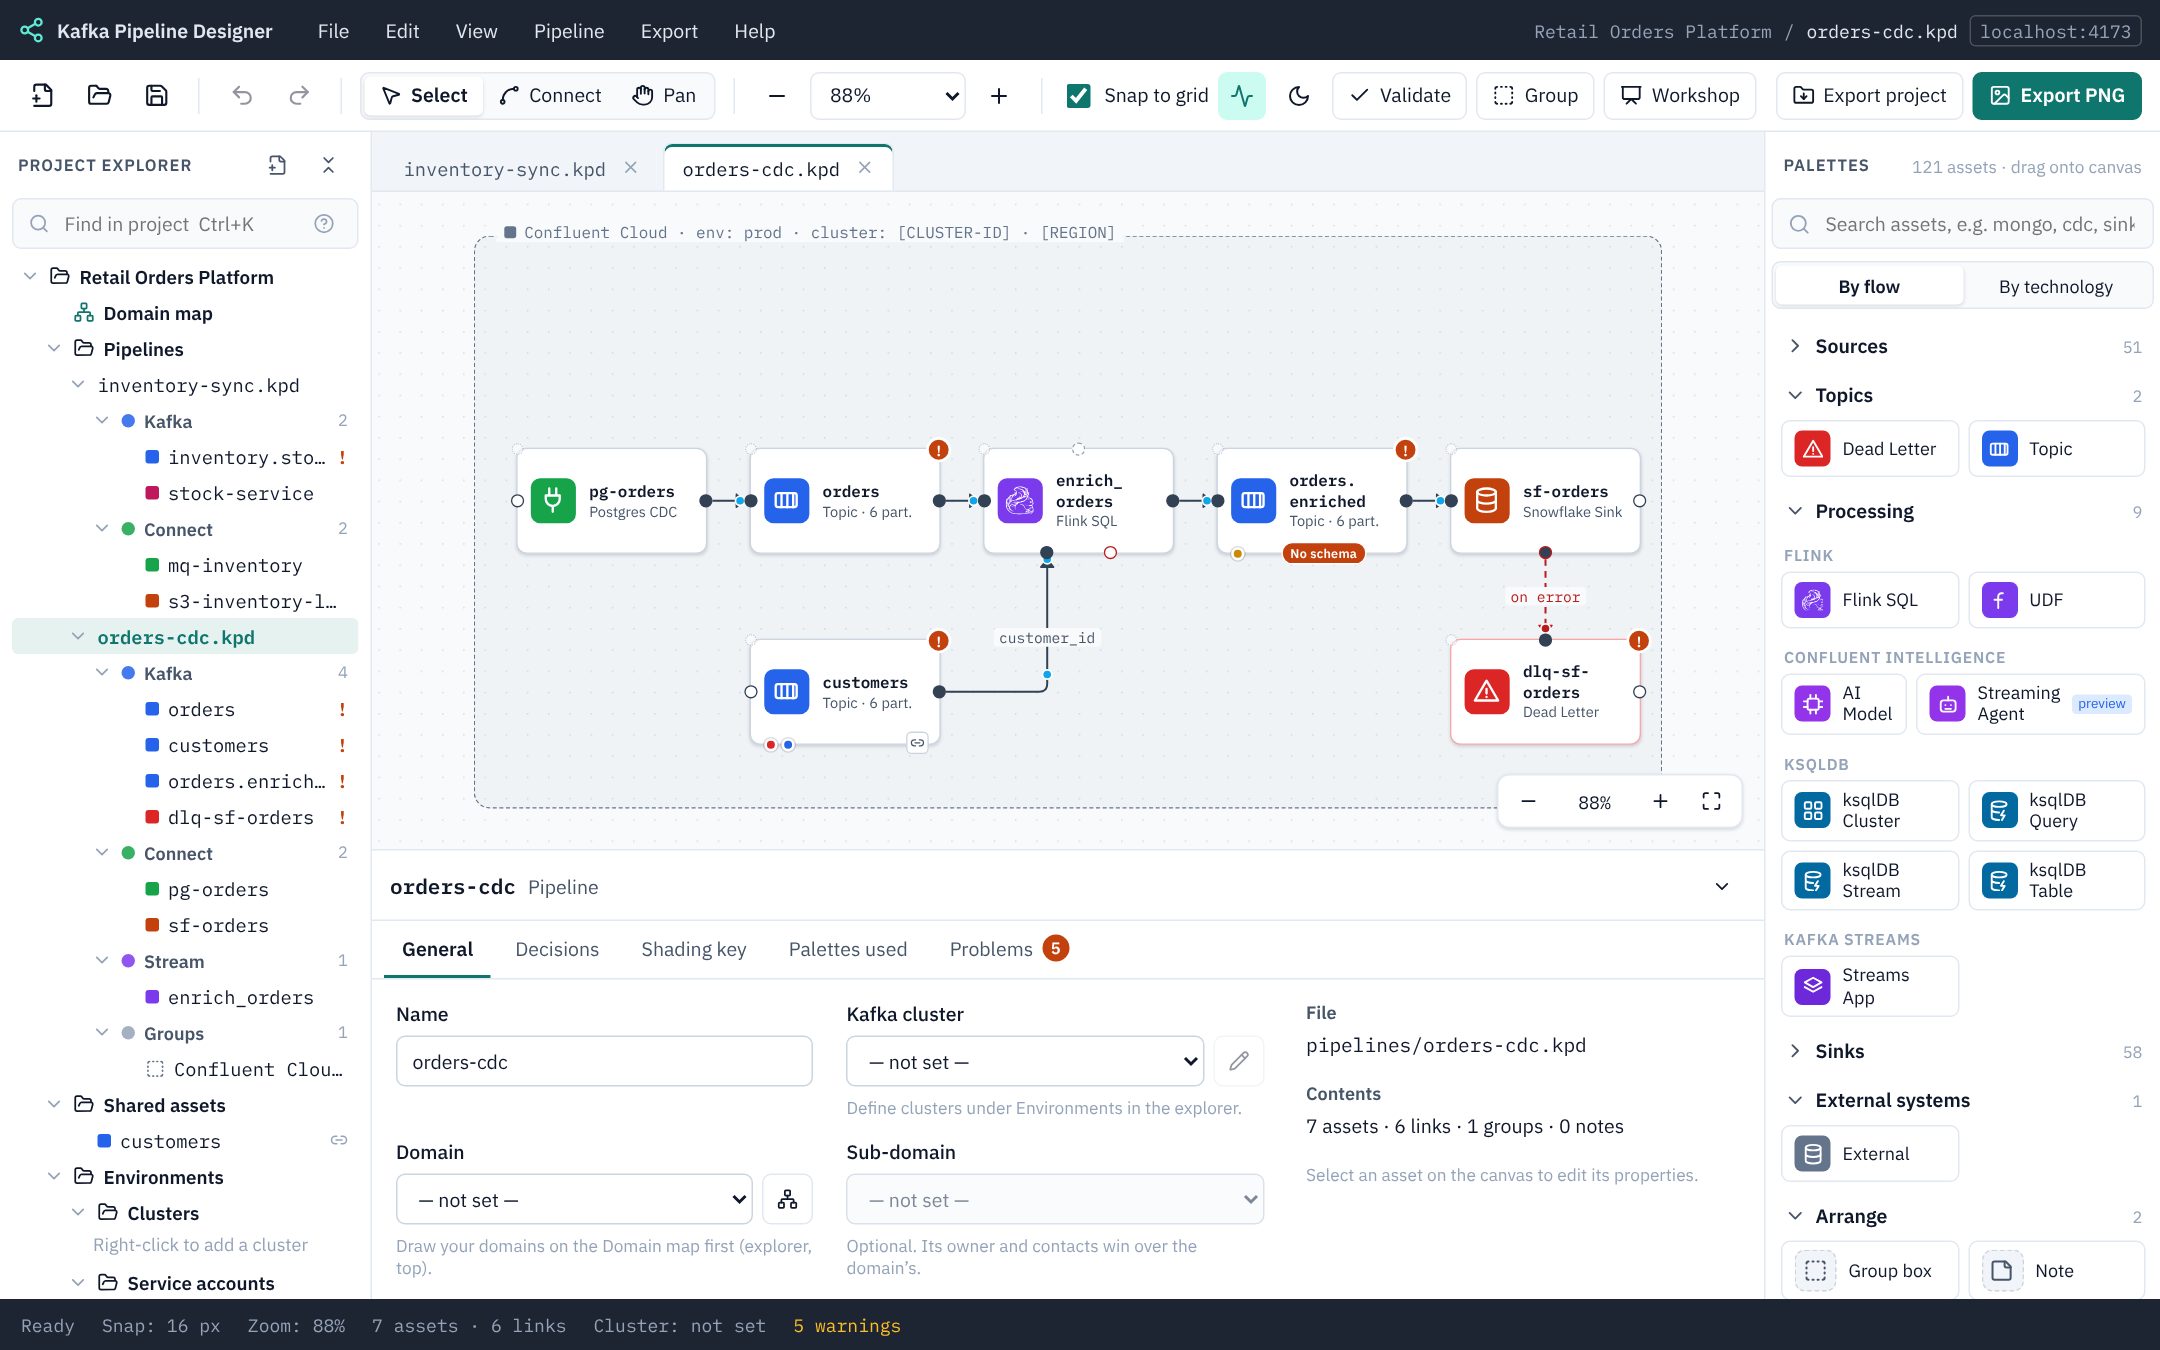
The first project KPD opens. Two small pipelines show the basics:
- orders-cdc: PostgreSQL CDC into an
orderstopic; a Flink statement enriches orders with a sharedcustomerstopic (a temporal join; its SQL is insql/orders-cdc/enrich_orders.sql), writesorders.enriched, and a Snowflake sink loads it with failures routed to a dead letter topic. - inventory-sync: IBM MQ into an inventory topic, then an S3 sink and a stock-service consumer group.
It also has a storyboard, Orders to the warehouse, telling the orders-cdc story in plain words; orders-cdc is linked to it (switch to Storyboard mode to open it, or use Show side by side on the pipeline).
It deliberately keeps a few warnings and hints (topic names that predate the naming standard, a topic without a schema, no cluster chosen yet), so the Problems tab has something to show.
Inclined Labs
A complete data product design for a fictional but realistic company: Inclined Labs (organisation code incl), which runs indoor wingsuit tunnels. It follows the Data Product Creation Framework and shows most of KPD in one pipeline, with 0 errors, 0 warnings and no outstanding permission advice.
- Ingestion: a cloud SQL Server database (an external system) feeds a SQL Server CDC connector, which writes three raw topics: customers, account credit and bookings.
- Process: three Flink statements map the raw rows to the Common Data Model in their own compute pool, with data quality rules and dead letter topics.
- Surface: four governed data products, shared assets with DataProduct metadata:
- DP-001 Customer registered, an event per new customer, read by the marketing CRM;
- DP-002 Account credit added, with no personal data, read by the finance ledger;
- DP-003 High-value booking, bookings over £5,000 enriched with a temporal join, read by sales alerts;
- DP-004 Live customer profile, a compacted materialized table, published to analytics with Tableflow.
- Seventeen Avro schemas named after their Schema Registry subjects, with personal data fields tagged PII and encrypted.
- The SQL of all seven Flink statements in its own files, one per statement, under Stream configuration → SQL (
sql/customer-data-products/). - Three Enterprise clusters (dev, test, prod), two stage compute pools, five least-privilege service accounts.
- Twelve design decisions and nine assumptions; shading by data product.
- A storyboard, Customer data products: the same design in business words, from the booking database to the four products and the teams that use them, with two open questions. The pipeline is linked to it.
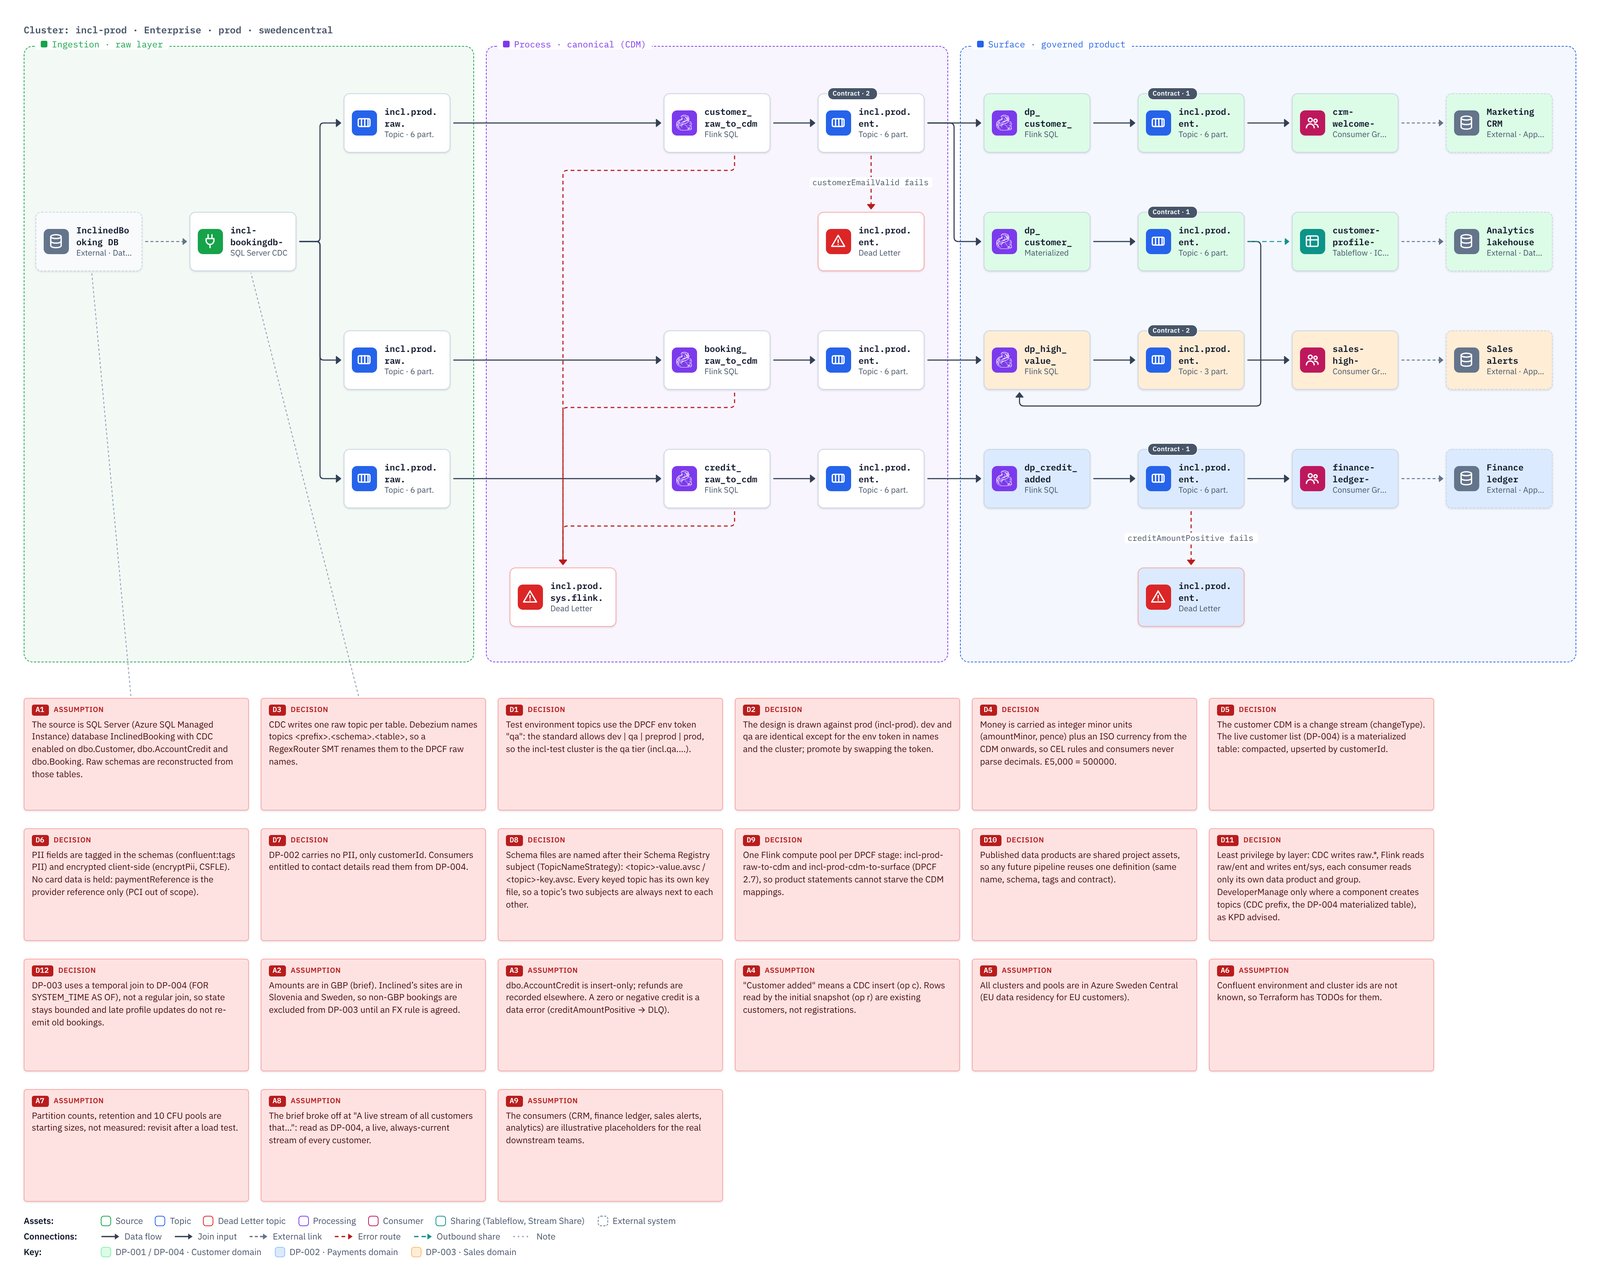
The sample was built by a script from its design document, a worked example of building a project from a design document.
Hello World Coffee (download)
The finished project from the Hello World tutorial: a PostgreSQL CDC source, two raw topics, a Flink join to a canonical order topic, two data products (each statement’s SQL in its own file), contract rules, three dead letter topics, service accounts, tags and catalogue metadata, decisions, actions and shading. It isn't one of the shared samples: download hello-world-coffee.zip and bring it in with File → Import project (.zip)…, and it is yours to change.